

The immediate problem: blind spots that cost time and money
When field supervisors can’t answer where a truck is, how long it idled, or why a maintenance call ran late, small errors compound into expensive delays. That gap is why teams deploy GPS fleet trackers to replace guesswork with verifiable position and event data. Even in high-stakes regions like the Gulf of Mexico, operators rely on real-time location and status feeds to coordinate crews, supplies and safety escorts; without that feed, decisions are delayed and compliance risks rise.
Define the problem precisely before you select metrics
Vague goals produce noisy reports. Start by naming the operational failure you must solve—late arrivals, unauthorized detours, excessive idle fuel burn, or missed preventive maintenance—and map one primary KPI to each failure. A concise set of measurable objectives prevents dashboards from becoming dashboards-of-everything that nobody trusts.
Core metrics every oilfield fleet should track
Track only what answers your named problems. Typical, high-value metrics include:
• Location and route adherence: timestamped position + defined route vs. actual path.
• Dwell and idle time: engine-on idling and stopped duration at critical nodes.
• Fuel consumption proxies: trip distance, idle time, and scheduled refuel events.
• Vehicle utilization: hours in service vs. available hours.
• Maintenance triggers and fault codes: mileage- and hours-based alerts plus CAN-bus fault captures.
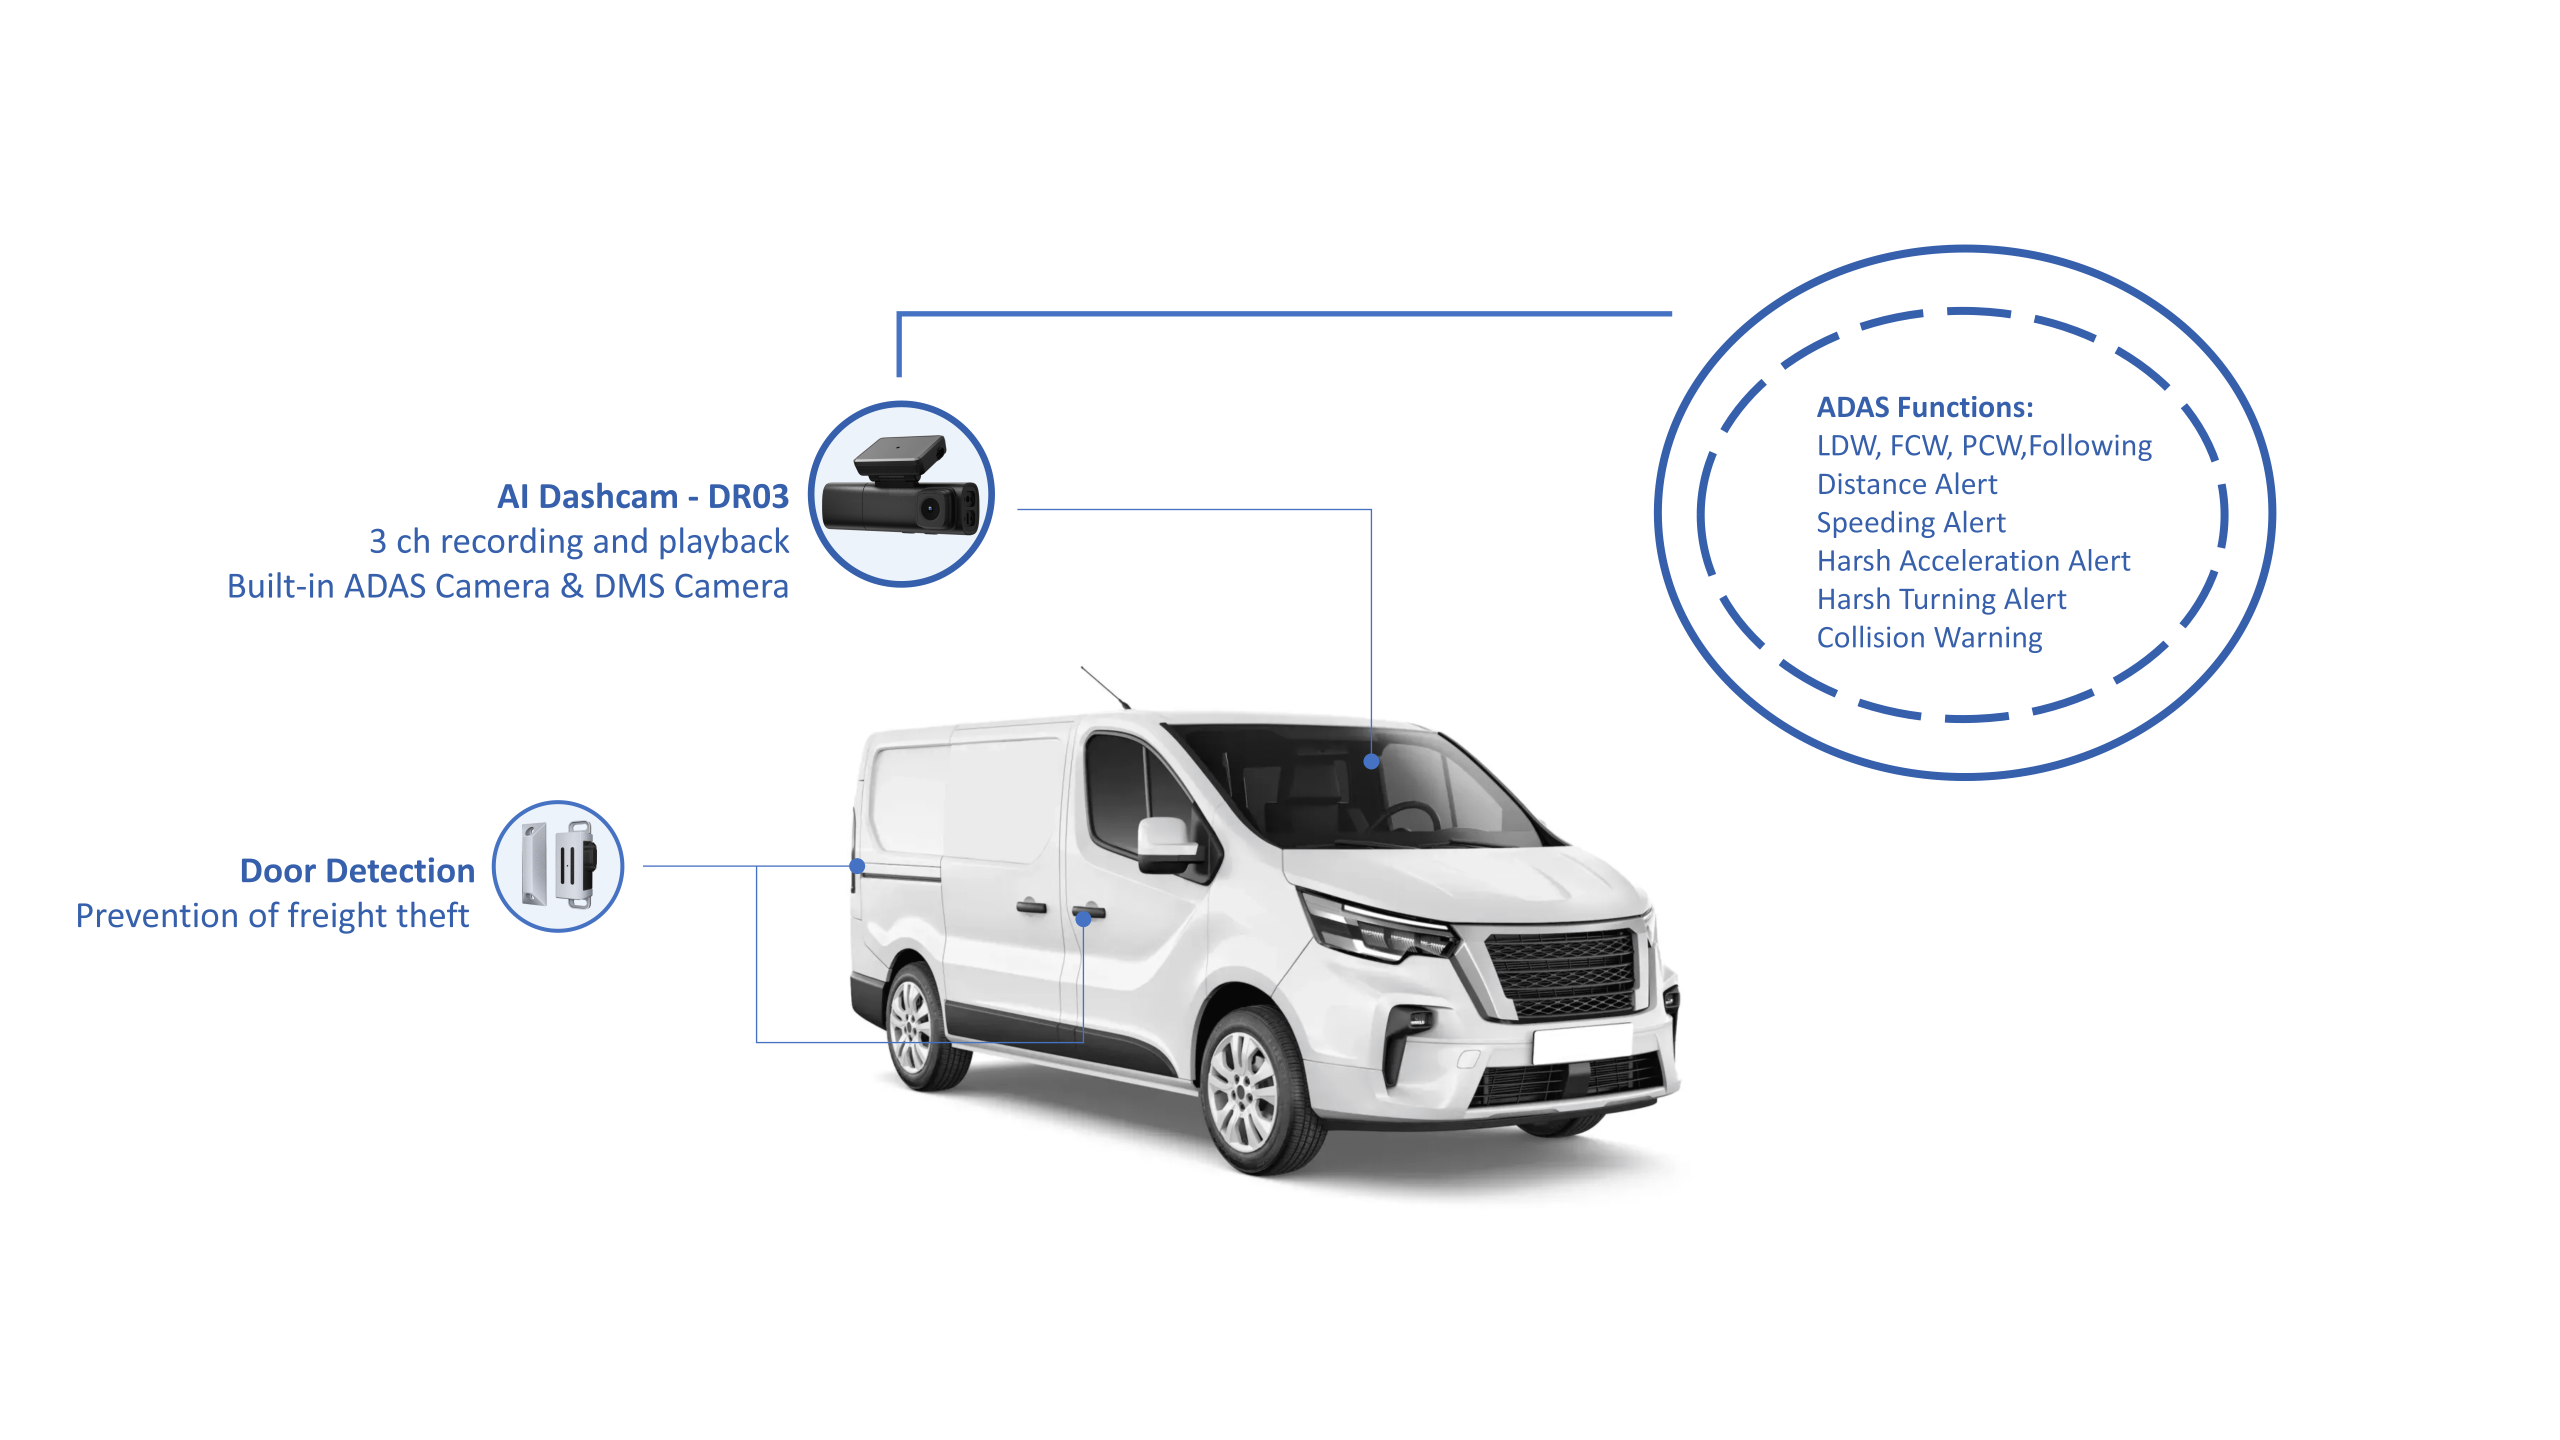
• Safety events: harsh braking, rapid acceleration, and geofence breaches.
• Trip-level audit trail: driver, start/stop times, and required attachments (photos, signatures) for compliance.
Data quality rules that separate signal from noise
Reports are only as useful as the underlying telemetry. Enforce these standards: sample frequency aligned to need (e.g., 10–60 seconds for route monitoring; longer for long-haul telemetry), consistent timestamps and timezones, device-level diagnostics (battery, GPS fix quality), and a single canonical fleet ID per vehicle. Normalize units and establish schema rules so automated reports don’t require manual reconciliation.
How to structure reports so stakeholders act
Design reports to answer the question the recipient cares about. Examples:
• Ops supervisor: daily exception list (late arrivals, geofence violations) with corrective action required.
• Fleet manager: weekly utilization, fuel proxy, and maintenance windows by vehicle.
• Safety officer: event summary with driver history and incident trend lines.
Include a brief executive summary line at the top — one sentence that tells the reader what changed and whether action is needed.
Common pitfalls and how to avoid them
Avoid these mistakes: mixing raw telemetry with KPI dashboards, over-reporting low-value events, relying on a single unreliable hardware model, and ignoring data retention and export capabilities. Mitigations: set strict event thresholds, run a pilot across vehicle types, and require hardware diagnostics and tamper alerts so missing data is visible, not invisible.
Choose a reporting approach that fixes the named problem
There are three practical approaches:
• Real-time monitoring + alerts: use when immediate intervention matters (e.g., convoy control, safety escorts).
• Aggregated KPIs with daily rollups: best for utilization and maintenance planning.
• Hybrid: real-time safety alerts plus scheduled KPI reports for business decisions. Match the architecture—edge buffering, cellular uplink policy, and API outputs—to that approach so data latency and completeness meet the use case.
Vendor and hardware checklist
When evaluating devices and platforms, look for these specifics: multi-band GNSS with fallback, CAN-bus integration, configurable transmit intervals, tamper detection, waterproof/IP-rated housings, OTA firmware updates, clear data retention and export policies, and documented security practices. For procurement, include a 60–90 day field trial across representative assets to validate real-world telemetry and install complexity. Also consider alternatives where necessary; for specialized trailers or remote equipment, remote-sensor edge modules can augment core trackers—evaluate whether a single hardware family covers all asset types or if mixed solutions are necessary.
Deployment checklist for a controlled rollout
Follow this sequence to avoid chaos: pilot on a small, diverse subset; validate data quality and battery/antenna placement; train dispatch and maintenance teams on exception workflows; roll out in waves; and enforce a fast feedback loop so installation and reporting edge-cases are fixed during rollout rather than after. Keep a change log tied to device serials so configuration drift is traceable.
Final synthesis: turn data into trustworthy operational answers
Be precise about the problem, collect the telemetry that directly answers it, and design reports that force a decision—no clutter, no guessing. My teams have led multiple field rollouts that reduced idle hours and improved maintenance compliance by focusing on those principles. When implementation choices matter, pairing proven hardware with a disciplined reporting framework keeps operators accountable and supervisors confident that data reflects reality, a practical outcome that platforms like BSJ are built to support.